
How to Run Llama 3 on an RTX 4090: What Fits in 24GB and How Fast It Really Is
Table of Contents Key Takeaways About the Author and How We Tested…

DeepSeek on Your Own Hardware: What It Really Takes to Run V4.1-Flash Locally
Table of Contents Why DeepSeek V4.1-Flash Broke the Local AI Playbook The…
iPhone 17 Pro in 2026: Why Last Year’s Flagship Is Now the Smarter Buy
Table of Contents What Changed in September 2026: The iPhone 18 Pro…
A20 Pro vs M6: Apple’s 2026 Mobile Application Processors and Which Chip You Actually Need
Table of Contents A20 Pro vs M6 at a Glance: The 2026…
AI Accelerators Explained: What NPU TOPS Actually Mean for the Laptop or Phone You Buy
Table of Contents What an AI Accelerator Is, and Why TOPS Became…
Pika AI Video App on Phone and Laptop: What It Actually Needs to Run Well
Table of Contents What Is the Pika AI Video Generator? Pika AI…
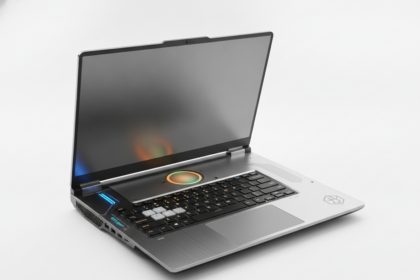
Which Laptop Should You Actually Buy Right Now? RTX Spark, ARM Battery Kings, and the Wait-or-Buy Question
Table of Contents Introduction The Short Answer: Buy This Laptop for Your…
How to Turn Off Apple Intelligence on iOS 27 and macOS 27 (And Reclaim 10GB of Storage)
Table of Contents Why Apple Intelligence Eats 10GB to 30GB of Storage…
Run AI Locally on Your Own PC: What llama.cpp Does, and Which Hardware You Actually Need
Table of Contents What llama.cpp Actually Does GGUF Quantization Shrinks the Model…
Claude API Pricing Explained: What Every Model Costs and When a Subscription Is Cheaper
Table of Contents Claude API Pricing Explained: How Anthropic Bills Per Token…